For teams shipping AI to production
AI that passes review before it reaches your customers.
Evals, guardrails, and agent systems built to hold up in front of auditors, customers, and regulators. Delivered by a cleared engineer who evaluates models for frontier AI labs and has shipped these systems in production.
Trusted by frontier AI labsOpenAIMetaGoogle- Faithfulness and hallucinationPASS
- Prompt injection and SSRFPASS
- Human approval gatesPASS
- Spend and rate controlsREVIEW
- Audit loggingPASS
- Data access scopingREVIEW
Every engagement ends with a scorecard like this, mapped to NIST AI RMF.
- OpenAI (via Mercor)
- Meta (via Handshake AI)
- Google (via Mercor)
- Mayo Clinic
- Signet Jewelers
- Polaris I/O
- JP Morgan Chase
- CACI / US Army
- Veterans Affairs
- Bayer
- Rivian
- College Board
- Live Nation
- The Infatuation
Services
Three ways to make your AI safe to ship.
AI Risk Audit
An outside read on the system you already have, before a launch, a board review, or a procurement questionnaire.
- Threat model of prompts, tools, and data paths
- Eval gap analysis against your real failure modes
- NIST AI RMF and EU AI Act mapping
- Written report and scorecard your team can act on
Evals and Guardrails
The test suite your model never had. Built to run in CI so regressions fail the build, not the customer.
- Calibrated LLM-as-judge rubrics with written rationales
- Red-team and prompt-injection test sets
- Deterministic gates that need no model call
- Retrieval quality measured with RAGAS
Safe Agent Delivery
Agentic systems designed with controls from day one, so a human signs off where it matters.
- Human approval gates at irreversible steps
- Scoped tool permissions and SSRF protection
- Per-agent spend and rate controls
- Audit logs your compliance team can read
Method
How every engagement runs.
- 1
Threat model
Map who uses the system, what it can touch, and what failure costs.
Risk register - 2
Evals
Turn those failures into tests with rubrics a reviewer can audit.
Eval suite in CI - 3
Guardrails
Add gates, permissions, and human sign-off where tests are not enough.
Controls + scorecard - 4
Monitor
Track drift, cost, and reviewer feedback after launch.
Alerts + reports
Production findings feed the next threat model
Work
Risk, control, result.
Filter by industry or kind of work. Every engagement opens to the full story, and the AI ones include an explainer at three levels of detail.
Frontier AI labs
Evaluation and expert data- OpenAI, via MercorOpenAIWriting-quality and presentation evals
Expert evaluation on OpenAI's Feather platform: catching low-substance AI writing in model-generated business documents and slide decks, each score on a calibrated 1 to 7 rubric with a written rationale.
Hundreds of OpenAI model deliverables scored
- Meta, via Handshake AIMetaCoding-agent evaluation
Hard coding tasks with hidden verifiers, then side-by-side agent runs ranked on independent evidence rather than self-reported success.
Hard tasks, hidden verifiers, evidence-backed rankings
- Google, via MercorGoogleExpert writing for model training
Expert writing for Google through Mercor, producing the human-written work Google's models learn from.
Selected as an expert writer
- Mayo Clinic
Clinical content validation pipeline
HealthcareAgentsEvals  Mayo Clinic
Website, patient sign-in, and content platform
Patient sign-in on Azure AD B2C, rolled out behind feature flags
HealthcarePlatforms- Signet Jewelers
Enterprise agent platform
RetailAgents - Polaris I/O
The AI SDK behind the Signals platform
TelecomGovernmentAgents - Polaris I/O
An agent workflow across three coding tools
Agents - Federal civilian agencies
Comprehension controls for a multi-agency RAG platform
GovernmentAgents - CACI / US Army
Predictive maintenance (PMx) for Army aviation and ground fleets
GovernmentPlatforms  Department of Veterans Affairs
Claim status and language access on VA.gov
Essential services, in more languages
GovernmentPlatforms Rivian
Vehicle parts sourcing platform
Supported R1T and R1S production
Platforms Live Nation / Ticketmaster
Event discovery at scale
From favorite artist to the next live show
Platforms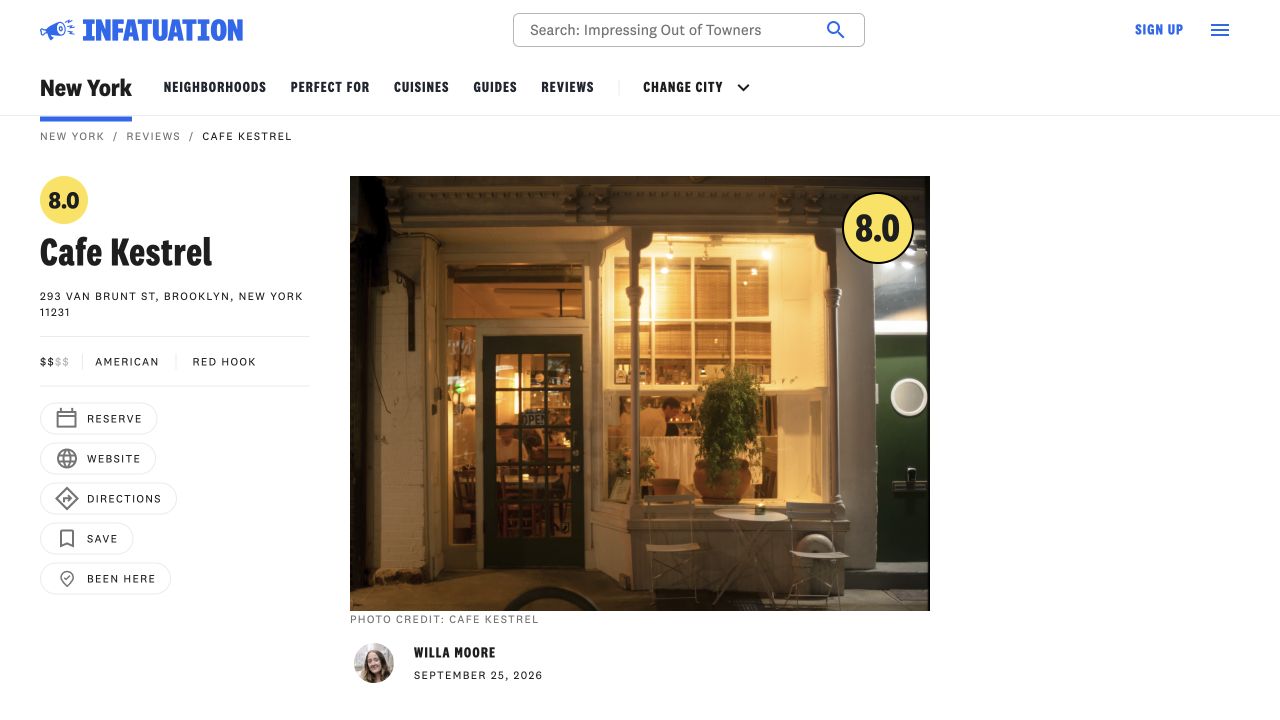 The Infatuation
Restaurant discovery and detail pages
Shared navigation through to every restaurant page
Platforms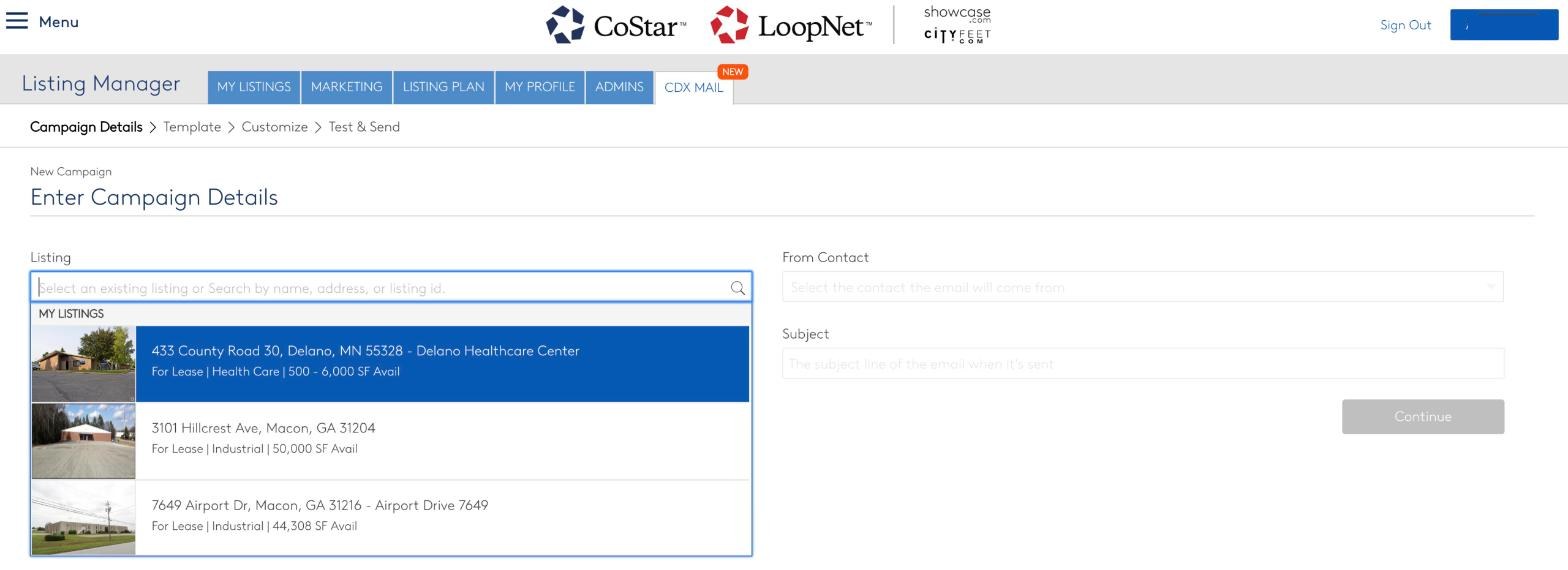 CoStar Group
CDX Mail: an email campaign platform on AWS
Batched, cancellable sends with event-driven metrics
Platforms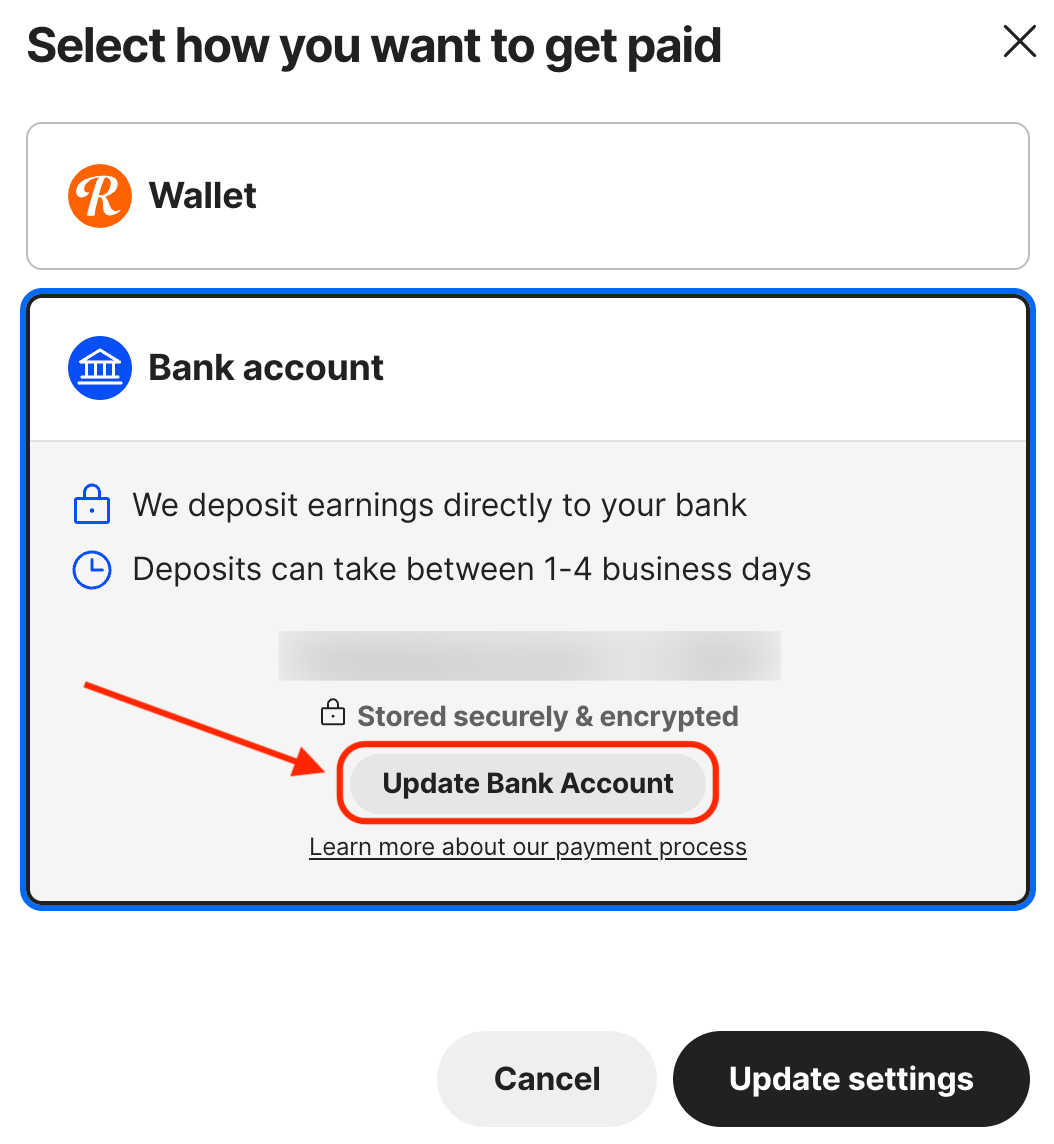 Etsy / Reverb
Seller payments with Plaid
Bank connection built into payments
RetailPlatforms- Book a risk reviewYour system next
Shipping AI somewhere a mistake is expensive?
A 30-minute risk review leaves you with the three risks worth fixing first.
Open tools we build in public
unslopify
A deterministic linter for AI-written prose. 27 named patterns, zero model calls, CI-ready exit codes. MIT licensed on PyPI.
Grasp
Plain-language briefs that explain merged code changes to every reader, from new engineer to executive.
See what an audit actually delivers.
A redacted sample report: threat model, eval results, scorecard, and the fix list, exactly as clients receive it.
Request the sample reportAbout
Engineering depth, policy fluency.
Fareez Ahmed founded V2 Software after a decade of shipping production systems for healthcare, finance, retail, and defense. He builds the evals and controls himself, and he has worked inside the review processes they have to survive.
His MA in International Affairs and Economics from Columbia means the regulatory side of AI is familiar ground, not an afterthought. He holds an active Secret clearance and works remotely from San Francisco and Dallas.
Shipping AI into a high-stakes setting?
Book a 30-minute risk review. You leave with the three risks worth fixing first, whether or not we work together.
Book a 30-minute risk review